Three products. One boundary.
A private assistant for your people, the layer that connects it to your systems, and the engine that trains your model. All of it runs inside your walls.
See all products →Recorded from the product. Meeting notes added with the + button become action items, decisions and an Arabic summary, streamed live from a model running on our own hardware.
Explore AE-1 →Frontier models know the world. They don’t know yours.
A rented model has never heard your Khaleeji customers, read your credit policy or seen how your best agents close a case. Sharq takes what your organisation already knows and turns it into a model that works inside your world, and belongs to you.
| Hosted frontier API |  | |
|---|---|---|
| Arabic adaptation | General-purpose Arabic, usually steered with prompts and examples | Fine-tuned on your own Gulf, Levantine or Egyptian conversations and scored on dialect evals |
| Data residency | Set by the provider’s hosting regions and data terms | Your racks, your cloud account in a UAE or KSA region, or Sharq’s in‑region hosting |
| Pricing model | Usage-based, usually per token | Pilot fee, then a platform plan, with compute billed at cost. The weights are yours to keep |
| Policy controls | Applied through system prompts and the provider’s safety settings | Trained into the model and checked on policy‑adherence evals before each release |
| Model updates | Released on the provider’s schedule | Retrained on your team’s corrections, on a cadence you approve |
What a run looks like. The console your team works in, from first dataset to a served model.
Open the consoleTry it. Switch runs, pause training, pick an eval to chart, change the base model and start a new run, then deploy it.
Fig. 1 · Sharq console, illustrative runArabic task success
How often the model gets the task right in your customers’ dialects, including code-switched Arabic and English.
- Baseline
- Your current stack, measured in weeks 1 to 2
- Pilot model
- The same cases, side by side, in weeks 9 to 10
Cost per task
What each completed task costs to run, compute included, compared with what you pay per task today.
- Baseline
- Your current stack, measured in weeks 1 to 2
- Pilot model
- The same cases, side by side, in weeks 9 to 10
Case throughput
Cases resolved per agent, per day, in the workflow the pilot targets.
- Baseline
- Your current stack, measured in weeks 1 to 2
- Pilot model
- The same cases, side by side, in weeks 9 to 10
How a pilot runs, week by week.
One workflow where your current stack is too expensive, too inconsistent or not allowed to leave the country. Twelve weeks later you have a private model and a benchmark to prove it.
Listen
We sit with your operations team and your records, and learn what the work actually is. One workflow, one owner, one number that has to move.
- You bring
- Call recordings, tickets, documents. The messy real thing.
- You get
- A data audit and a written target for the pilot.
Train
Your data is cleaned, stripped of personal details and labelled by dialect. We fine-tune an open model on it, inside your environment, and iterate against Arabic evals every few days.
- You bring
- Two hours a week from a domain expert to review samples.
- You get
- A model that speaks like your best agents, and the dataset behind it.
Prove
Side by side with what you use today, on live cases, on the outcome you named in week one.
- You get
- A benchmark report: task success, cost per task, throughput.
Improve
The model joins the team. Accepted edits and escalations become the next training set, on a cadence you approve.
- You get
- Quarterly refreshes, each one re-checked against the same evals.
One platform, from raw records to a served model.
Every stage runs where your data lives. Your team can watch, approve and roll back at each one.
Data foundry
Calls, chats, scans and records become training-ready material, with private details removed before anything is touched.
- Arabic OCR for scanned forms and letters
- Personal data removal, logged
- Dialect and code-switch labelling
- Versioned datasets
Guided training
Choose a base model and a target; the platform picks the method, the hardware fit and the schedule.
- Qwen, Llama, Mistral, Falcon and Jais families
- LoRA and full fine-tuning
- Runs on your GPUs or ours, in‑region
- Every run reproducible from its config
Regional eval lab
Judged on the Arabic your customers actually write and say, and on the rules your regulator cares about.
- Gulf, Levantine, Egyptian and Maghrebi suites
- Policy-adherence and safety checks
- Red-team sets in Arabic and English
- A regression gate before every release
Private serving
The finished model runs as an endpoint inside your walls, with an audit trail your governance team can read.
- Your VPC, your racks, or Sharq in‑region
- Model registry with lineage
- Residency attestation per deployment
- Feedback captured for the next refresh
Nothing leaves the country. Not the data, not the weights.
Sovereignty is not a checkbox on a vendor’s questionnaire. It is where the model physically runs, who holds the keys, and whether you could walk away tomorrow with everything intact.
- Your own racksOn-premisesSharq deploys into your data centre. The rack in the picture is the kind we ship into.
- Your cloud accountUAE or KSA regionRuns in your VPC with your IAM. We never hold a copy of your data.
- Sharq hosted, in-regionDubaiFor teams without their own GPUs. Dedicated tenancy, residency attested per deployment.
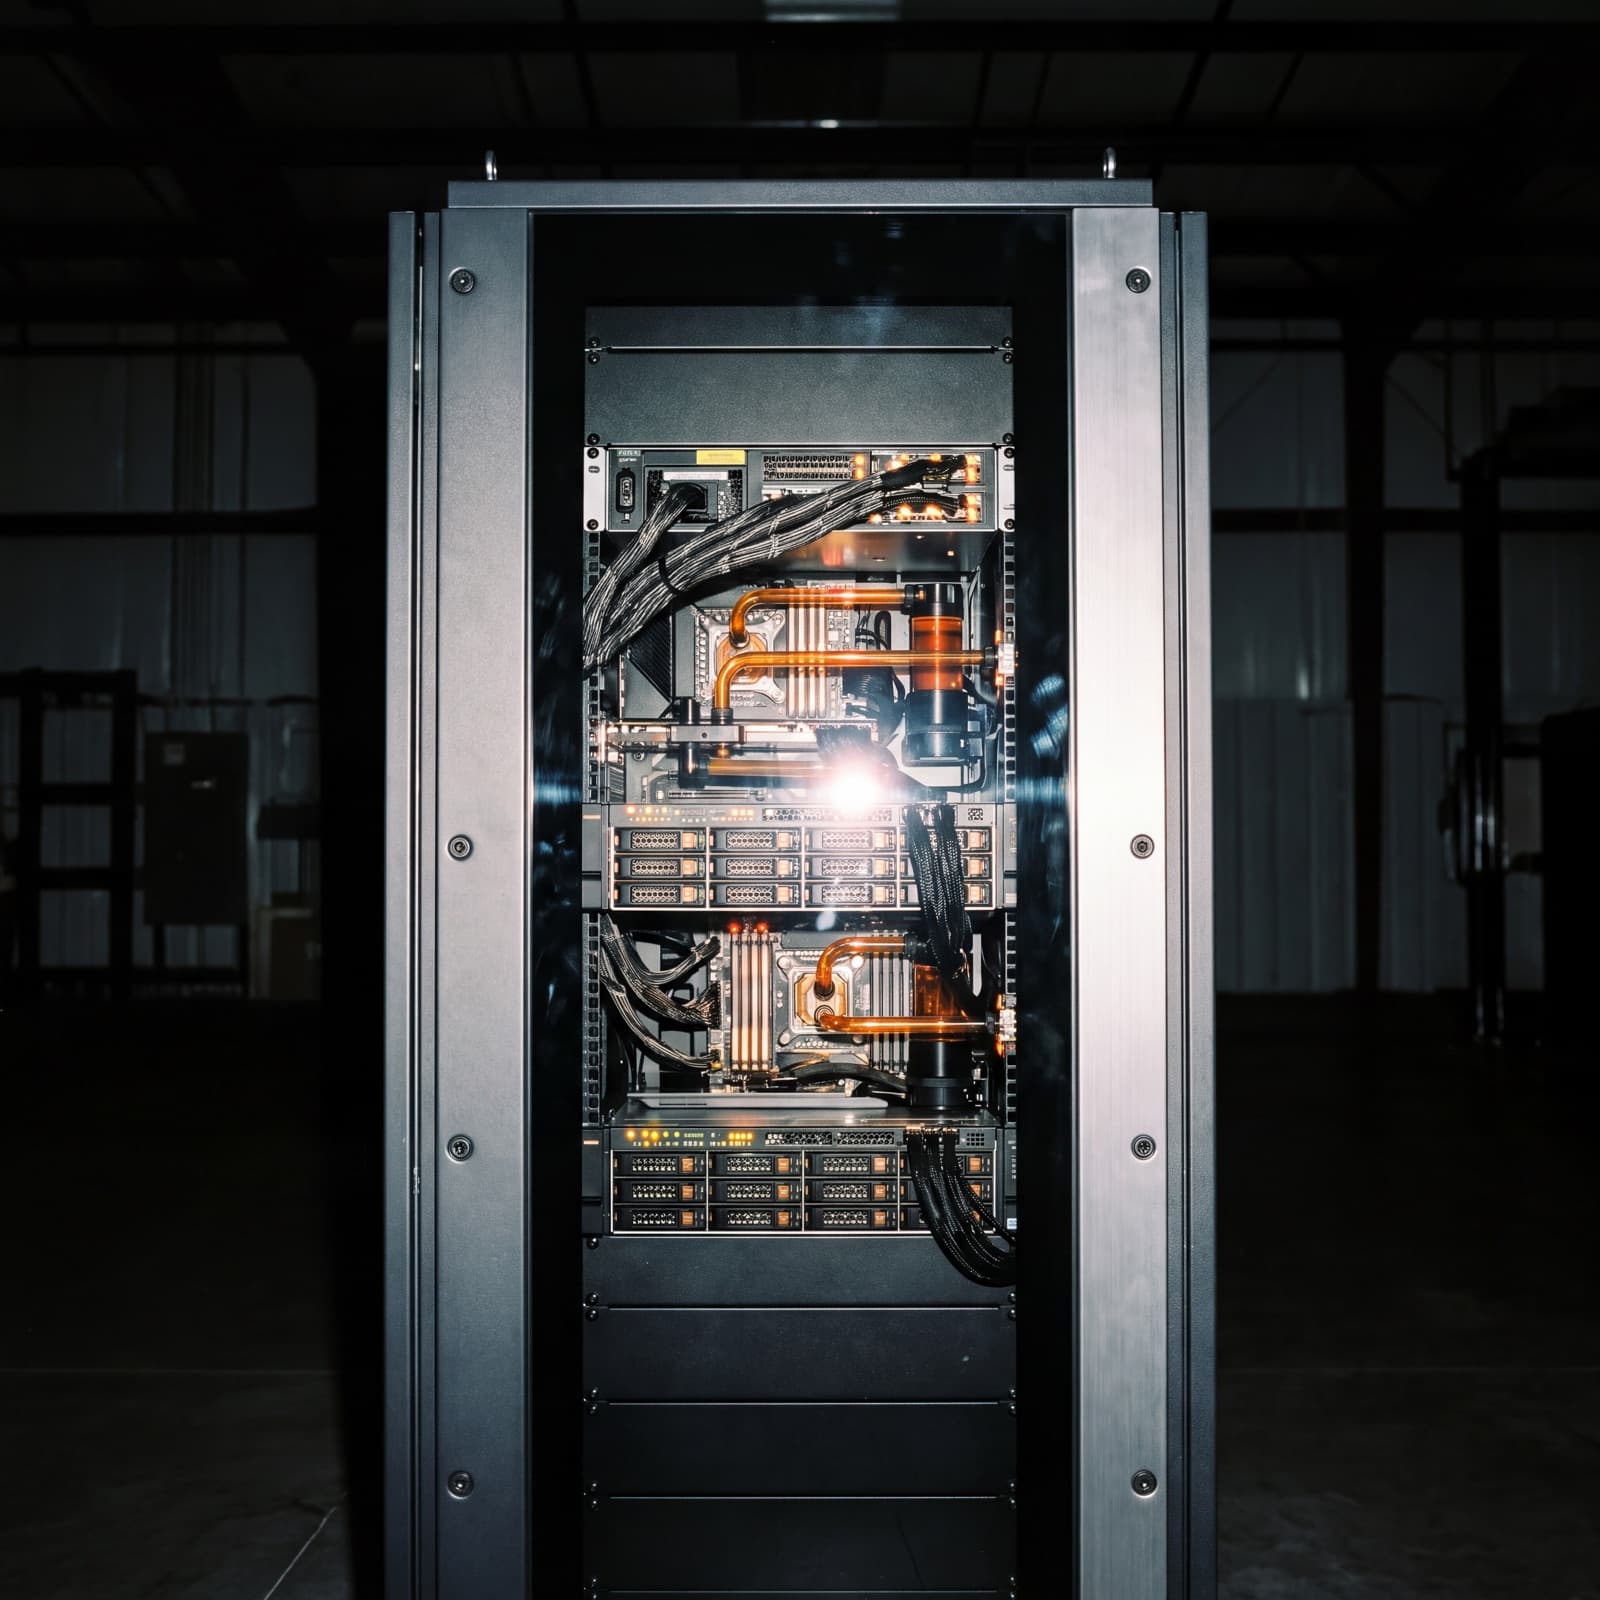
Built for the work that costs you the most.
We start where the volume is high, the language is local and the current tooling is either expensive or not allowed.
Banking
الخدمات المصرفيةRetail and corporate banks with Arabic-speaking customers and strict residency rules.
- Collections conversations
- KYC document review
- Complaint triage and response
- Credit policy assistant
Telecom
الاتصالاتContact centres handling millions of code-switched conversations a month.
- Agent assist in dialect
- Call summarisation and QA
- Churn-risk conversation flags
- Self-service chat
Government
الجهات الحكوميةEntities that cannot send a citizen’s record to a foreign cloud, full stop.
- Citizen-service case handling
- Arabic form and letter processing
- Policy question answering
- Bilingual document drafting
Questions teams ask before a pilot.
Anything missing, ask us directly. Conversations are confidential and we reply within one business day.
The model weights, the curated dataset behind them, and the evaluation suites used to judge them. You can export all three at any time and run the model without Sharq.
Wherever you say: your own racks, your cloud account in a UAE or KSA region, or Sharq’s in‑region hosting. Nothing is copied outside the environment you approve.
No. Sharq engineers run the pipeline. Your side contributes what only it can: a domain expert for a couple of hours a week to review samples and outcomes.
Dedicated evaluation suites for Gulf, Levantine, Egyptian and Maghrebi dialects, Arabic–English code-switching, cultural alignment and policy adherence, alongside the business metric the pilot was scoped on.
Open-weight families such as Qwen, Llama, Mistral, Falcon and Jais, sized to the task. Most production pilots land between 7B and 27B parameters, which is what keeps cost per task low.
Corrections, escalations and outcomes from real work are folded back into the training set on a cadence you approve. Each refresh is re-checked against the same evals before it is promoted.
Tell us about the workflow.
Pick the one where your current stack is too expensive, too inconsistent or not permitted. We will come back with a pilot plan, a data checklist and a number to beat.